


Lexicons and AI in Communications Surveillance: A practical guide to designing, testing, governing and modernizing communications surveillance using lexicons and AI

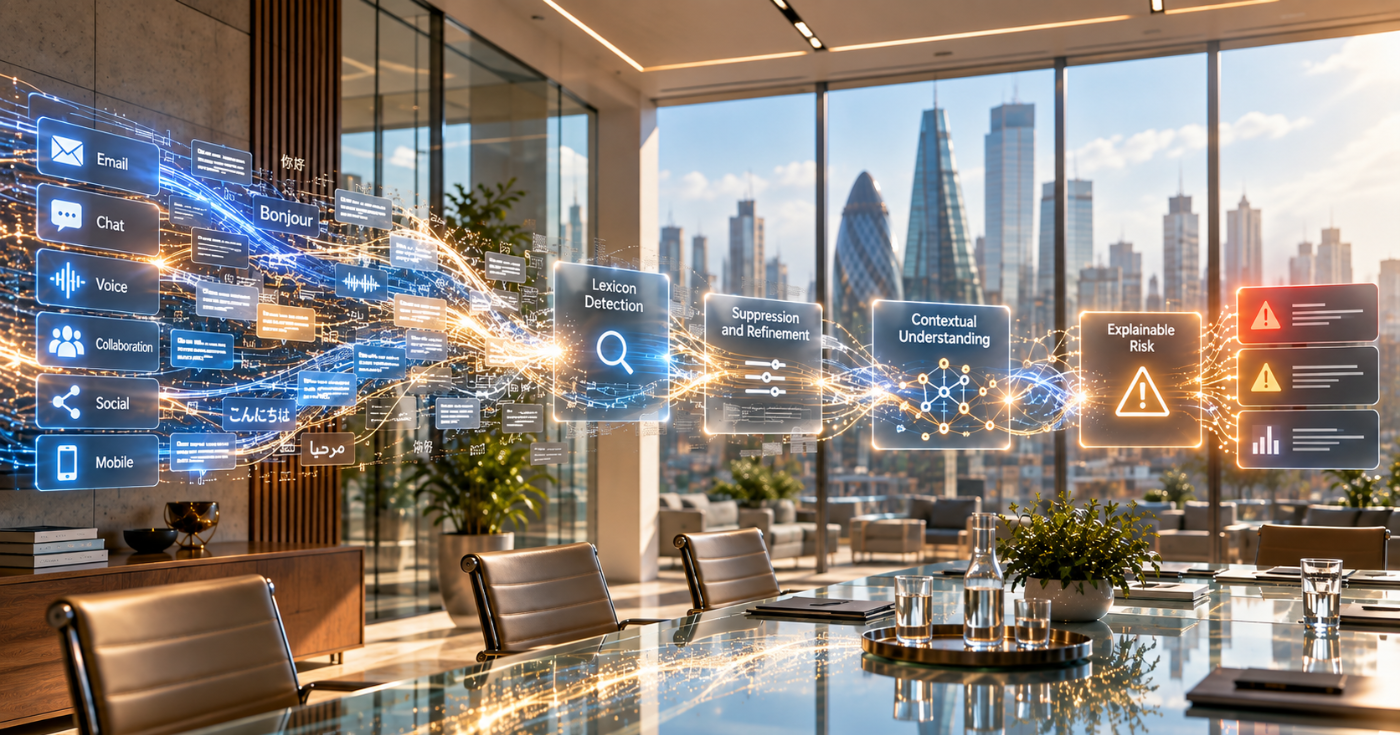
Lexicons remain useful for surveillance and regulatory frameworks in digital communications governance and archiving because they are explicit, controllable and auditable.
They become unreliable when a firm treats words as proof of behavior. The practical objective is therefore not to abandon lexicons, but to place them inside a governed detection system that combines context, behavioral signals, suppression, scoring, multilingual controls and human review.
How to use this guide
This guide is written for surveillance and communication monitoring practitioners who design, operate, test or oversee communications surveillance programs as part of a regulatory and compliance framework. It explains what a lexicon is, how to convert a risk into detection logic, how to measure performance, and how to decide when deterministic matching should be supplemented by semantic or agentic AI.
The main conclusion is operational: a lexicon should be managed as one component of a surveillance control, not as a standalone dictionary. Every term should map to a behavior and scenario; every scenario should have evidence, exclusions, thresholds and an owner; and every alert outcome should feed testing and change control.
The practitioner path
| Stage | Primary question | Output |
| 1 Define | What behavior are we trying to detect? | Risk statement and scenario |
| 2 Design | Which language, context and metadata indicate it? | Signals, rules and suppressors |
| 3 Test | Does the logic find relevant examples without overwhelming review? | Precision, recall and volume evidence |
| 4 Deploy | How will alerts be scored, routed and explained? | Controlled production configuration |
| 5 Learn | What do dispositions and missed cases tell us? | Tuning backlog and governed changes |
| 6 Modernize | Where can AI add context or coverage? | Layered lexical and AI control |
Scope and terminology
The term lexicon is used here in its practical surveillance sense: a structured set of words, phrases, linguistic patterns and associated rules used to identify communications that may indicate regulatory, conduct or compliance risk. Some vendors use lexicon more narrowly to mean an exact-match list; others use it broadly to include Boolean logic, proximity, exclusions and concept groups. Practitioners should document which meaning applies in their environment.
What a lexicon does
A lexicon translates a known risk concept into observable language. If a firm wants to identify attempts to move a conversation away from monitored channels, it might look for platform names, requests to call a personal number, or phrases that suggest switching channels. The lexicon supplies explicit linguistic indicators. The surrounding scenario determines how those indicators are interpreted.
| Element | Meaning | Example |
| Risk domain | A broad category of regulatory or organizational risk | Market abuse |
| Behavior | A type of action within the domain | Front running |
| Scenario | A specific manifestation of the behavior | Trading ahead of a client order |
| Rule | Logic that evaluates language, metadata or contextual signals | Order language near timing language |
| Lexicon signal | A word or phrase that supports the rule | before the announcement |
| Suppressor | Logic that prevents benign or duplicated content from progressing | Public news quotation |
| Score | A value used to distinguish stronger from weaker candidates | Threshold based on combined signals |
| Alert | A candidate that meets the conditions for human or AI Agent review | Case in the monitoring queue |
Keyword, lexicon and scenario are not interchangeable
A keyword is a single searchable item. A lexicon groups terms and patterns around a concept. A scenario combines those signals with conditions that represent a plausible behavior. This separation matters because a phrase such as “personal phone” can be relevant to off-channel activity, but it is not itself evidence that off-channel activity occurred.
A useful design chain starts with the risk obligation and the behavior it targets, frames that behavior as a scenario, identifies the trigger signals and supporting evidence that indicate it, applies suppressors to filter out noise, and then produces a score that drives an alert and, ultimately, an investigation outcome.
Why lexicons remain important
- They are explainable. A reviewer can see which phrase matched and which rule evaluated.
- They are controllable. A firm can add or retire terms in response to a new product, platform or regulatory concern.
- They are auditable. Ownership, rationale, versions, approvals and test results can be documented.
- They are effective for explicit, known indicators, especially when precision can be improved with context and exclusions.
- They give firms a practical way to preserve and migrate established surveillance knowledge.
Why traditional lexicon surveillance struggles
The core weakness is semantic. Lexical matching can establish that a pattern appeared; it cannot, by itself, establish what the speaker meant or what behavior occurred. The phrase “do not tell anyone” may refer to confidential information, a planned surprise party or a sensitive employee matter. Conversely, an evasive instruction may be expressed without any term the firm anticipated.
| Failure mode | Typical cause | Operational effect |
| False positive | A risky term appears in benign context | Reviewer time is consumed clearing noise |
| False negative | Risk is expressed indirectly or with unseen language | Relevant conduct may not alert |
| Duplicate alerting | Quoted text or email-thread echoes are reprocessed | The same event appears repeatedly |
| Coverage drift | Slang, products, channels or business practices change | A once-valid lexicon becomes stale |
| Language gap | Literal translation misses idiom, morphology or code-switching | Coverage differs by region or team |
| Governance debt | Terms lack owners, rationale or test evidence | Changes become difficult to defend |
Precision and recall create a real tradeoff
Precision asks: of the communications selected, how many were relevant? Recall asks: of the relevant communications present, how many did the control find? Broad terms may improve recall while damaging precision.
Narrow combinations may improve precision while missing indirect or unfamiliar language. A program should decide which tradeoff is acceptable for each scenario rather than pursue a single global target.
The maintenance burden is structural
A lexicon is not finished when it goes live. It must be updated for new channels, products, regions, abbreviations, typographical variations, evasive language and reviewer findings. Multilingual coverage multiplies this burden because equivalent intent is not represented by one-to-one translation. Without a disciplined operating model, additions accumulate faster than obsolete terms are removed.
Translating risk into a surveillance scenario
Start with the behavior and evidence, not a list of suspicious words. A good scenario describes who may do what, to whom, under which circumstances, and what observable traces the activity would leave in communications or metadata.
Step 1 Write the risk statement
Use a narrow statement that can be tested. For example: “An employee may attempt to move a business conversation involving a client order from an approved channel to a personal or unmonitored channel.”
Step 2 Describe positive and negative examples
Collect representative true-risk examples and plausible benign examples before building rules. Positive examples should include explicit, indirect and unusual forms. Negative examples should include policy reminders, technical support, personal conversations, public news and quoted text. This prevents the lexicon from being shaped only by obvious misconduct phrases.
Step 3 Decompose the behavior into signals
| Signal role | Question | Off-channel example |
| Trigger | What language initiates the scenario? | move this to Signal |
| Supporting evidence | What makes the trigger more credible? | Client or order language in the same conversation |
| Context | Who, where and when? | Trader and external client shortly before activity |
| Suppressor | What benign explanation should prevent progression? | Policy training or approved support workflow |
| Severity factor | What should increase priority? | Repeated attempts or a high-risk employee population |
Step 4 Define the rule
A rule may require a trigger plus supporting evidence, proximity between concepts, a participant condition, or a minimum score. Record the rationale for every condition. If a condition exists only because it lowered volume during tuning, determine whether it also makes risk sense; otherwise the rule may be optimized for workload rather than control effectiveness.
Step 5 Define the alert explanation
Before deployment, write the explanation a reviewer should see: behavior, matched language, supporting context, suppressors considered, score and source communication. If the team cannot explain why a candidate should be reviewed, the scenario is not ready.
Building a lexicon
Design the lexicon as structured data
| Field | Purpose | Example |
| Phrase | The text or pattern to match | send it to my personal |
| Concept | The meaning group represented | Channel switching |
| Behavior | The governed behavior mapping | Unauthorized channels |
| Language and locale | The language and relevant regional variant | English United Kingdom |
| Match type | Exact, stem, regex, semantic or other | Exact phrase |
| Case and accent handling | How matching treats case and diacritics | Case insensitive, accent sensitive |
| Weight | Contribution to candidate scoring | High when paired with order language |
| Source | Why the phrase was added | Confirmed case, policy, regulator, SME |
| Owner and dates | Accountability and review cycle | Surveillance team, quarterly review |
Use concept groups, not flat lists
Organize terms by concepts such as concealment, channel switching, transaction intent, inducement, confidentiality or coordination. This allows rules to combine concepts without duplicating phrases. It also makes change impact easier to assess: adding a term to a concept can affect every scenario that uses the concept.
Treat exact matching as an explicit design choice
Exact matching is useful when the required evidence is literal and auditability is paramount. It is also brittle. Spaces, accents, morphology and formatting can change the outcome. For customer-owned lexicons, record whether matching is case-sensitive and accent-sensitive, and test the precise tokenizer behavior for each language and channel.
Include exclusions with equal discipline
An exemption list is itself a surveillance control. Every exclusion should have a reason, owner, approval and test. Avoid broad exemptions that can suppress genuinely risky messages merely because a benign phrase appears somewhere in the conversation.
Practical quality review
- Remove duplicate phrases and normalize obvious formatting inconsistencies.
- Confirm each phrase maps to a behavior and scenario, not only a broad risk label.
- Test capitalization, accents, punctuation, spacing and common transcription variants.
- Review high-volume phrases individually before enabling them in production.
- Check that phrases can be explained to an investigator without relying on hidden assumptions.
- Maintain a retirement process for obsolete, duplicative or consistently unproductive terms.
Suppression is part of lexicon design
False-positive reduction should be designed with the scenario, not added only after alert volumes become unmanageable. A mature program can reduce predictable noise at several logical points, but each suppressor must have a defined scope, rationale and test. The broader the suppressor’s effect, the stronger the evidence needed to show that relevant communications remain covered.
| Suppression principle | Purpose | Typical examples | Primary control risk |
| Source filtering | Exclude clearly non-relevant automated traffic | System notifications and approved service accounts | A relevant source is classified too broadly |
| Content classification | Identify routine or standardized material | Out-of-office messages, signatures and disclaimers | Substantive content is mistaken for boilerplate |
| Duplicate control | Avoid repeated review of unchanged content | Quoted threads and repeated text | New content is incorrectly treated as a duplicate |
| Scenario exclusions | Prevent known benign contexts from satisfying a rule | Approved policy language or documented exemptions | Exclusion logic is too broad |
| Risk thresholding | Prioritize stronger combinations of evidence | Candidates below a governed threshold | Weak but valid cases are consistently hidden |
| Contextual review | Assess whether the full context supports genuine risk | Public news, personal discussion or benign references | Reasoning is not validated, traceable or monitored |
Design suppressors by unit of effect
Document whether an exclusion affects a text span, message, conversation, signal or alert candidate. Apply the narrowest effective scope. Standard footer text may be excluded from producing a signal without removing the substantive message, while duplicate controls should ignore unchanged quoted content without disregarding new material.
Measure what suppression removes
For each material suppressor, retain counts before and after suppression, sampled examples, exception findings and the scenarios affected. When possible, replay a representative dataset with the suppressor enabled and disabled. Volume reduction is not sufficient evidence: the program must also show that relevant risk was not disproportionately removed.
Use contextual suppression carefully
AI-based suppression can evaluate the full conversation and distinguish a benign public-news reference from an attempt to misuse information. It should be deployed as a governed layer with validation, a retained rationale, human oversight, monitoring and a path to inspect suppressed candidates. Contextual suppression improves precision only when the model has been tested against the firm’s real communication mix.
Testing and tuning lexicons
A useful test set contains confirmed or expert-labeled positive examples, difficult benign examples, different channels, relevant languages, short and long conversations, quoted material, attachments or transcripts where applicable, and examples from multiple employee populations. Separate the data used for development from the data used for final validation. Use a balanced scorecard
| Measure | What it tells you | Caution |
| Precision | Share of selected items judged relevant | Can look strong if the rule is too narrow |
| Recall | Share of known relevant items detected | Requires credible positive examples |
| Alert rate | Operational volume per communication or employee | Low volume does not prove effectiveness |
| Unique event rate | How many distinct matters alerts represent | Duplicate controls must be applied consistently |
| Disposition mix | How reviewers classify alerts | Reviewer inconsistency can distort results |
| Time to review | Operational cost and usability | Faster closure may hide superficial review |
| Suppression rate | How much is filtered at each stage | High suppression requires coverage testing |
| Language coverage | Which languages are actually monitored | Configured coverage may differ from observed usage |
Run tests in four passes
- Unit test each phrase and rule condition using controlled examples.
- Replay historical communications to estimate alert volume, duplicates and concentration by term.
- Review a stratified sample of alerts and suppressed candidates with subject-matter experts.
- Shadow-run the control in production before it affects the live queue, then compare predicted and actual workloads.
Diagnose at the term and scenario level
Do not tune only at the model total. Identify which phrase, language, channel, desk or suppressor produces the error. A scenario can have acceptable aggregate precision while one term creates most of the noise or one region receives weak coverage.
Close the learning loop
Reviewer dispositions should generate structured feedback, but they should not automatically retrain or rewrite the control. Sample reviewer consistency, distinguish false positive from low priority, and require approval before feedback changes production logic.
Lexicon governance
Lexicon governance connects detection logic to regulatory obligations, operational ownership and evidence. A regulator or internal audit team should be able to reconstruct what the firm monitored, why, how it was tested, what changed and how outcomes were reviewed.
| Governance object | Minimum evidence |
| Risk mapping | Obligation, risk domain, behavior and scenario rationale |
| Lexicon register | Terms, concepts, language, match behavior, source and owner |
| Rule specification | Triggers, supporting evidence, proximity, metadata, exclusions and scoring |
| Test pack | Dataset description, labels, metrics, samples, limitations and sign-off |
| Change record | Request, impact assessment, approvals, version, deployment and rollback plan |
| Monitoring pack | Volumes, precision indicators, disposition trends, drift and exceptions |
| Model or AI record | Purpose, model version, prompts or configuration, validation and oversight |
| Issue log | Known gaps, compensating controls, owners and remediation dates |
Use risk-based review frequencies
High-volume, high-severity or fast-changing scenarios should be reviewed more often than stable low-volume controls. Trigger an out-of-cycle review after a regulatory event, a confirmed miss, a new channel, a major organizational change, a material language shift or a sharp change in alert distribution.
Separate authority
The people who propose terms, approve changes, validate performance and review alerts may overlap in smaller firms, but the roles should remain explicit. Material production changes need independent challenge, particularly when they reduce alert volume.
Design for multilingual coverage
Multilingual surveillance is a coverage problem before it is a translation problem. Firms first need to know which languages appear, where, in what volume, across which channels and employee populations. Detection should also account for mixed-language messages, transliteration and regional usage rather than assuming each communication belongs to one language.
Choosing the right coverage method
| Language profile | Preferred approach | Why |
| Material recurring language | Dedicated localized detection and testing | Volume justifies deeper language-specific control |
| Established internal terminology | Governed firm-specific lexicon and validation | Preserves relevant business and regional knowledge |
| Rare or unexpected language | Risk-based contextual analysis with human oversight | Dedicated localized models may not be proportionate |
| Voice communication | Validated speech recognition followed by language-appropriate surveillance | Detection quality depends on transcription quality |
| Mixed-language message | Language identification at an appropriate level and code-switching tests | Whole-message classification can miss shifts |
| New language or script | Technical compatibility and representative-data assessment | Parsing and word-boundary behavior affect detection |
Do not translate terms mechanically
For each concept, collect native-language expressions, idioms, abbreviations, industry jargon, regional variants, transliteration and deliberate obfuscation. Use local subject-matter experts and representative data. Validate meaning in context, not merely linguistic equivalence.
Separate transcription from detection
In voice surveillance, automatic speech recognition creates the text; the surveillance control analyzes the resulting text later. Measure both stages. A detection miss may result from an inaccurate transcript, a language-identification error, a lexicon gap or the behavior model itself.
Monitor actual language use
Compare the languages observed in captured communications with those included in surveillance. Review unexpected and low-volume languages rather than assuming they are immaterial. The outcome should be a documented decision: dedicated localized coverage, a firm-specific lexicon, governed contextual analysis, another compensating control or an accepted and approved limitation.
Adapt detection by channel
| Channel | Lexicon considerations | Common noise source |
| Threads, subjects, quoted text, signatures and attachments | Repeated replies and legal footers | |
| Chat | Short messages, abbreviations, emojis and rapid context shifts | Fragmented conversational context |
| Mobile messaging | Slang, deleted or edited messages and channel switching | Personal and business content mixed together |
| Voice | Transcription errors, speakers, timing and acoustic quality | Misheard names, numbers and jargon |
| Collaboration tools | Files, reactions, threads and multiple workspaces | Automated notifications |
| Attachments | Extraction, OCR, file type and embedded content | Boilerplate and inaccessible formats |
A single phrase list should not be assumed to behave consistently across channels. Test segmentation, message boundaries, participant metadata and suppressors separately. A phrase that is meaningful in a one-to-one chat may be low value in a large broadcast channel.
Move from lexical to semantic and behavioral detection
Modern surveillance uses several detection layers. They should be viewed as complementary controls with different strengths, not a simple replacement sequence.
| Layer | Primary question | Strength | Limitation |
| Exact lexical | Did this phrase appear? | Transparent and deterministic | Brittle and context-poor |
| Rule based | Did defined signals occur together? | More precise and explainable | Requires ongoing design and tuning |
| Semantic | Does the communication express this meaning? | Finds paraphrases and indirect language | Needs validation and explanation |
| Behavioral | Does activity fit a risk pattern? | Uses participants, history and events | Data integration and causality are complex |
| Agentic | How should context be interpreted and acted on? | Can reason across nuanced or novel cases | Prompt, model and oversight risks must be governed |
Use AI where lexical logic is weakest
- Interpreting whether risky language is benign in the full conversation.
- Finding idiomatic, inferred or evolving expressions that do not use known terms.
- Extending risk detection into rare or low-volume languages where dedicated lexicons do not scale.
- Identifying novel manifestations of a licensed behavior for investigation or scenario research.
- Prioritizing candidates using contextual evidence while preserving deterministic triggers.
Keep the evidence visible
An AI-supported alert should show the behavior under consideration, relevant passages, participant and channel context, the reasoning or evidence supporting the decision, and the relationship to the governed scenario. A score without evidence is not a useful explanation.
Apply AI without losing control
Regulatory discussion has moved beyond whether AI may be used. The focus is now how firms govern it. FINRA’s 2026 Annual Regulatory Oversight Report confirms that firms may use GenAI within supervisory systems, while emphasizing integrity, reliability, accuracy, formal approval, comprehensive documentation, testing, ongoing monitoring, prompt and output logs, model-version tracking and human-in-the-loop review.
For agents specifically, FINRA highlights the need to track actions and decisions and to establish guardrails and oversight. This supports AI as a viable path when the control remains accountable and auditable; it does not create an exemption from existing supervision, communications or recordkeeping obligations.
The FCA’s 2025 review of off-channel communications observed firms integrating natural language processing alongside lexicon-based models and exploring AI to filter false alerts.
The FCA’s Market Abuse Surveillance TechSprint also examined AI and advanced analytics as ways to improve alert accuracy and identify complex market-abuse patterns that traditional rules struggle to detect. These sources support a layered model in which AI improves surveillance outcomes while the firm remains responsible for control design, vendor oversight and effectiveness.
Define a bounded purpose
State whether the model generates candidates, expands coverage, suppresses likely false positives, prioritizes alerts or assists investigators. Each purpose has different validation and human-oversight requirements. Avoid one broad AI component that changes all stages without separable evidence.
Validate on representative communications
Performance varies by firm, language, channel and business activity. Validate against the customer’s communication mix before production, including difficult benign examples and rare positive cases. Record limitations and areas where human review remains essential.
Govern prompts and model changes
Instruction-based models can adapt more quickly than retrained models, but prompt wording materially affects output. Treat prompts, examples, thresholds and model versions as controlled configuration. Test updates, preserve versions, monitor drift and maintain a rollback path.
Retain human accountability
AI-assisted detection should support, not replace, accountable surveillance decisions. Human reviewers should be able to challenge results, escalate issues and record a disposition. Sampling should include both generated alerts and suppressed candidates.
Use layered assurance
- Technical validation of inputs, outputs, latency and failure modes.
- Detection validation using labeled communications and scenario-specific metrics.
- Operational validation of queue volume, explanations, workflow and reviewer consistency.
- Governance validation of documentation, approvals, access controls, audit trail and monitoring.
- Ongoing review for drift, changes in language use and unequal performance across populations.
Practical playbook: Off-channel communications
Objective
Identify attempts to move business-related communications from approved systems to personal or unmonitored channels.
Detection design
| Component | Examples |
| Trigger concepts | Personal number, alternative platform, disappearing messages, move or switch channel |
| Supporting concepts | Client, order, price, deal, transaction, confidential matter |
| Metadata | External participant, regulated employee, high-risk desk, timing near transaction activity |
| Suppressors | Policy reminders, technical-support instructions, approved channel migration, personal social plans |
| Contextual AI role | Distinguish a business-evasion request from an unrelated personal conversation |
| Reviewer evidence | Matched phrases, surrounding messages, participants, channel history and prior similar events |
Tests
- Explicit requests naming a prohibited platform.
- Indirect requests such as “use the other number” in a business context.
- Policy and training messages that mention prohibited platforms benignly.
- Code-switching and local slang for popular messaging services.
- Short chat sequences where the risk meaning emerges across several messages.
Practical playbook: Concealment and information handling
Objective
Identify language suggesting that a person wants to hide, delete, restrict or misuse information in a way relevant to the firm’s obligations.
Detection design
| Component | Examples |
| Trigger concepts | Delete, keep quiet, avoid writing, do not share, erase or conceal |
| Supporting concepts | Compliance, regulator, client, transaction, confidential information, investigation |
| Suppressors | Routine retention instructions, privacy notices, approved information barriers, personal surprises |
| Semantic role | Identify intent to conceal even when no curated phrase appears |
| Behavioral role | Consider repeated deletion requests, timing, participants and related transaction activity |
| Reviewer evidence | Full conversation, information classification, participant roles and sequence of events |
A concealment lexicon should not equate confidentiality with misconduct. Confidentiality is often legitimate. The scenario needs evidence that secrecy is being used to evade a control, hide an activity or misuse protected information.
Practical playbook: Market conduct
Objective
Identify communications that may support behaviors such as collusion, manipulation, misuse of material information or trading ahead of client activity.
Detection design
Market-conduct scenarios rarely work well as single-term alerts. Combine communication evidence with transaction concepts, roles, instruments, timing and where available trade or order activity. Use lexicons to identify explicit language and semantic models to find indirect coordination, inference and coded expressions.
| Evidence type | Illustrative question |
| Action | Is someone proposing, instructing or confirming an activity? |
| Entity | Which instrument, client, issuer, venue or counterparty is involved? |
| Intent | Does the communication suggest coordination, advantage or concealment? |
| Timing | Does it occur before an announcement, order or market event? |
| Relationship | Are the participants colleagues, clients, competitors or external contacts? |
| Context | Is the content analysis, public commentary, a hypothetical example or an operational discussion? |
Historical and owned lexicons and migration
Many firms already possess years of terms, scenarios and local knowledge. A bring-your-own-lexicon approach can preserve that asset while moving it into a modern pipeline. Migration should not be a file import exercise alone.
Migration checklist
- Inventory source lexicons, owners, languages, scenarios and historical performance.
- Remove duplicates and separate terms from rules, exemptions and metadata conditions.
- Map each phrase to a governed behavior and scenario.
- Document exact-match behavior, including case, accents, spacing and tokenizer constraints.
- Validate any language-specific email splitting or message segmentation.
- Apply standard suppressors deliberately and record any exceptions.
- Replay representative communication data and report phrase-level volume and impact.
- Verify scoring, labels, reviewer evidence, reports and audit history in the target workflow.
- Establish an ongoing update and retirement process after go-live.
Operating models and roles
| Role | Core responsibility |
| Compliance risk owner | Defines the risk appetite and approves scenario coverage |
| Surveillance design | Translates risks into behaviors, scenarios, rules and evidence |
| Language specialist | Validates idiom, locale, transliteration and cultural meaning |
| Data and technology | Maintains capture, parsing, metadata, integration and lineage |
| Model validation | Independently tests performance, limitations and change impact |
| Operations | Reviews alerts, applies dispositions and identifies recurring failure modes |
| Model risk or AI governance | Oversees AI purpose, versions, validation, monitoring and accountability |
| Audit | Assesses whether design and execution evidence support the stated control |
Monthly control review
The monthly control review tracks alert and suppression volume broken down by scenario, term, language, channel, and population. It examines disposition trends, reviewer agreement, and review time. It also captures any new confirmed cases, known misses, and relevant regulator or policy changes.
The review looks at high-volume and zero-hit terms, along with new slang and recurring benign patterns that surface. It assesses AI performance, override rates, drift indicators, and any material configuration changes. Finally, it documents open limitations, compensating controls in place, and upcoming tests planned.
How Shield combines lexicons with AI
Shield’s approach illustrates how lexicons can remain a useful part of surveillance without carrying the entire control. The architecture maps risk domains to behaviors and scenarios, uses lexicons for explicit suspicious language and red flags, and combines those signals with machine-learning context, transparent rules, scoring, suppression and investigator workflows.
Shield’s AmplifAI suite reflects this practitioner model: specialized agents support language and coverage expansion, noise reduction, risk reasoning, investigations and governed alert resolution.
Where lexicons remain useful
Shield supports curated out-of-the-box detection and customer-owned lexicons. A customer can onboard exact-match phrases, associate them with behaviors and languages, and run them through the same general detection, scoring, suppression, reporting and review framework. This preserves firm-specific knowledge and gives practitioners a controlled way to address local risks, topics and languages.
How the traditional limitations are reduced using Shield
| Traditional problem | Modernized response in Shield’s approach |
| A term alerts in benign context | Metadata, message, content, rule, score and AI-based suppression reduce predictable noise |
| The same text alerts repeatedly | Repeated-text controls and email echo cancellation reduce duplicate signals |
| A fixed list misses indirect meaning | Semantic, machine-learning and generative AI layers evaluate context, intent and nuanced behavior |
| A rare language lacks a full lexicon | An emerging Language Expansion Agent is designed to apply contextual LLM detection for rare or unmonitored languages |
| A static rule misses novel behavior | Surveillance can analyze behaviors for subtle or evolving risk patterns |
| AI black box | Alerts remain inside governed investigation, escalation, case-management and audit workflows with human review |
| Customer knowledge is lost in migration | Bring Your Own Lexicon retains customer-defined phrases while adding validation, testing and pipeline integration |
Lexicons vs AI: Shield’s approcah
Shield does not require practitioners to choose between lexicons and AI. Lexicons provide transparent, deterministic evidence for known risk language. Machine learning and contextual AI add classification, entities, intent, semantic meaning and broader conversational understanding. Suppressors and scoring prevent every match from becoming an alert. Agentic capabilities extend detection and noise reduction where fixed language rules are weakest.
This layered design significantly reduces the main problems associated with traditional lexicon-only surveillance: excessive false positives, duplicate alerts, limited context, missed idiom, static coverage and the burden of maintaining separate language packs. It does not remove the need for validation. Exact-match behavior remains exact matching; contextual models must be tested in each environment; language coverage decisions must be documented; and human reviewers remain accountable.
The future of lexicon surveillance is not a larger dictionary. It is a controlled system in which deterministic language signals, contextual models, behavioral evidence and human judgment reinforce one another. Shield’s model places AI at the heart of that system while retaining lexicons where their precision, transparency and auditability are valuable.
For surveillance practitioners, the goal is a surveillance control that can explain what it found, understand enough context to reduce noise and increase efficiency, adapt to new risks and channels, such as AI chat prompts, and preserve a defensible record of every decision.
FAQ: Understanding Lexicon Design, AI and Surveillance Governance
Are lexicons still useful for communications surveillance, or should firms move entirely to AI?
Lexicons remain valuable because they’re explicit, controllable, and auditable — a reviewer can see exactly which phrase triggered a match and why. They become a liability only when a firm treats a keyword match as proof of misconduct rather than one input into a broader system. The recommended approach isn’t replacing lexicons with AI, but embedding them inside a governed detection framework that adds context, behavioral signals, suppression, scoring, and human review around the deterministic language matching.
What’s the difference between a keyword, a lexicon, and a surveillance scenario?
A keyword is a single searchable term. A lexicon groups related terms and patterns around a concept (like “channel switching” or “concealment”). A scenario goes further, combining those lexicon signals with contextual conditions — participants, timing, metadata — to represent a specific, plausible risky behavior. This distinction matters because a phrase on its own, such as a reference to a personal phone number, isn’t evidence that off-channel activity actually happened; it only becomes meaningful once it’s tied to a scenario with supporting context.
Why do traditional lexicon-only systems generate so many false positives?
The core issue is that lexical matching identifies language, not intent or behavior. A risky-sounding phrase can appear in an entirely benign conversation, while genuine misconduct can be expressed in language the lexicon never anticipated. This creates a structural tradeoff between precision (how many flagged items are actually relevant) and recall (how many truly relevant items get caught) — and lexicons also require constant maintenance as slang, products, and channels evolve, which is amplified across multiple languages.
Where does AI genuinely add value that lexicons alone can’t provide?
AI is most useful in exactly the places where fixed language lists struggle: interpreting whether a risky-sounding phrase is actually benign given the full conversation, catching paraphrased or indirect language that never uses a “known” trigger word, extending coverage into rare languages without building a full dedicated lexicon, and weighing behavioral or historical context alongside the text itself. The guidance is to deploy AI for a specific, bounded purpose — such as suppression, classification, or prioritization — with validation and human oversight, rather than as one broad, unaccountable layer.
What does it mean to “govern” a lexicon, and why does it matter for regulators or auditors?
Governing a lexicon means every term is mapped to a defined behavior and scenario, every rule has documented rationale and test evidence, and every change goes through impact assessment, approval, and version control. This matters because a regulator or internal auditor should be able to reconstruct exactly what the firm monitored, why, how effectiveness was tested, and how outcomes fed back into tuning — something a flat, ownerless keyword list simply can’t support. Digital Communications Governance and Archiving (DCGA) programs are built on this same principle: surveillance controls are only defensible when there’s a documented, auditable trail connecting policy, detection logic, and outcomes.
How does a governed lexicon program fit into a firm’s broader Digital Communications Governance and Archiving (DCGA) strategy?
A lexicon and AI detection framework doesn’t operate in isolation — it depends on DCGA to actually capture, preserve, and make communications available for surveillance in the first place. If archiving is incomplete, communications from certain channels are missing, or retention isn’t properly enforced, even the most sophisticated lexicon and AI layer will have blind spots it can’t detect. A mature DCGA foundation ensures the full population of communications — email, chat, mobile messaging, voice, and collaboration tools — is reliably captured and retained, giving the surveillance program something complete and defensible to actually analyze, test, and audit.
How does a DCGA solution like Shield support lexicon-based surveillance for market abuse and conduct risk?
A DCGA solution like Shield captures, retains, and governs communications data across channels in one consistent source of truth, then layers lexicons and AI-driven detection on top to put that data in context — connecting explicit language signals with behavioral, participant, and timing evidence rather than treating a single risky phrase as proof of misconduct. Since market abuse and conduct risks are often expressed indirectly or evolve faster than any static term list, that combination of governed data, transparent lexicons, and contextual AI is what makes earlier, more precise detection possible, while keeping final judgment on the alert with accountable human reviewers.
Related Articles
The Future of AI-Driven Surveillance Is Here. Most Firms Just Haven’t Deployed It Yet.
Subscribe to our newsletter
Gain access to exclusive insights, industry influencers, and thought leaders in
Digital Communications Governance and Archiving (DCGA).