Go Back
On-demand

A Watchful Eye: Regulators double down on AI in compliance

From the new Chief of AI at the Department of Justice to the FCA’s recent AI guidance, regulators are just starting to leave breadcrumbs about what they expect from firms. But you need to understand the ramifications FAST.

Before you can explain to regulators how you’re using it, you need to understand it.

How does AI impact surveillance? What about data management? Most importantly, what does effective AI look like?

Our panel of experts dove deep into how AI dominated the conversation in surveillance and archiving functions. They explained how your team could leverage modern systems while maintaining good governance to mitigate real risks. This webinar was designed to provide you with actionable insights and strategies to stay ahead in the ever-evolving landscape of compliance.

The discussion explored:

  • Understand the latest regulatory expectations and how they impact your compliance strategy.

  • Learn how AI can enhance your data management and surveillance capabilities.

  • Understand trends across model risk management and best practices for implementing AI-driven solutions in your compliance framework

Speakers

Dr. Shlomit Labin

Dr. Shlomit Labin

Shield VP Data Science

Shlomit has a B.Sc. in Physics and Computer Science, an M.Sc. in CS, and a Ph.D. in cognitive psychology. Her experience in the industry spans several decades in leading tech companies in Israel, both large and small. Previously, Shlomit served as the vice president of Research at medCPU, the vice president of Research at LawGeeks, and the head of research at Verint.

Lore Aguilar

Citi Director of Surveillance Design, Research, and Analytics

Lore is Director of Surveillance Design and Research within Independent Compliance and Risk Management at Citi. He is responsible for the global design of trade and communication surveillance, as well as the strategic adoption of advanced methodologies. Prior to joining Citi, Lore was director of surveillance design at FINRA’s Market Regulation Department. Lore holds a PhD in Economics from the University of Minnesota – Twin Cities.

Alvin Huang

AWS AI in Capital Markets SME

Alvin Huang is a Financial Services Specialist for Worldwide Business Development at Amazon Web Services with a focus on artificial intelligence and machine learning. He has over 20 years of experience in the financial services industry, and prior to joining AWS, he was an Executive Director at J.P. Morgan Chase & Co. where he managed the North America and Latin America transaction surveillance teams and led the development of global trade surveillance.

Alex de Lucena

Shield Director of Product Strategy

Alex brings over a decade of experience in global finance and communications surveillance. Before joining Shield, Alex held senior positions at Macquarie Group. Alex’s expertise spans risk management, compliance, and data science, with a proven track record in overseeing and deploying communications surveillance programs.
  • Transcript

    A Watchful Eye: Regulators Double Down on AI in Compliance

    Shield Insiders In-Focus
    Speakers

    • Alex DeLucena, Director of Product Strategy, Shield (Moderator)
    • Alvin Huang, Market Development, Financial Services, AWS
    • Lore Aguilar, Director of Surveillance Design & Research, Surveillance Intelligence Unit, Citi ICRM Surveillance
    • Dr. Shlomit Labin, VP, Data Science, Shield Financial Compliance


    Introductions

    Alex: Good afternoon, or good morning, or good evening, depending where in the world you are. Thank you for joining our webinar, A Watchful Eye: Regulators Double Down on AI in Compliance. There’s a bit of a trick in the title — do we mean doubling down on the compliance of AI, or on how AI can be used in compliance? We’re going to talk about both today. We have a really great panel and a lot to cover. I’ll just pick from whoever I see first on Zoom. Alvin, who are you?
    Alvin: Hey, Alex, very nice to be here — thanks for having me. My name is Alvin Juan. I’m on the market development team for financial services here at AWS, with a focus on machine learning and generative AI. I’ve been with AWS a little over six years. Prior to joining, I spent twenty years in financial services, most recently at JPMorgan, where I was on their compliance surveillance team. So this topic is near and dear to my heart.
    Shlomit: Hello, everybody, nice to meet you. I’m Shlomit Labin, VP of Data Science at Shield Financial Compliance. I’ve been in the AI industry for many years, leading AI-driven solutions in many domains, and in the past few years in the financial compliance domain.
    Alex: We’re waiting on Lore Aguilar, who heads up a data science function within communication surveillance for Citi. Myself, I’m Alex DeLucena, Shield’s Director of Product Strategy. Prior to that, I worked in compliance and headed up a comms surveillance function, and now I’m on the vendor side.
    Lore: Lore Aguilar .I’m Director of Surveillance Design and Research within the Surveillance Intelligence Unit of Citi’s ICRM Surveillance. I have a group of data scientists who look for ways to innovate and improve our surveillance design for markets, information barriers, and electronic communication surveillance.

    Framing: Three Questions About AI in Compliance

    Alex: Let me frame our conversation around a contradiction that sits at the heart of AI adoption in compliance. On the one hand, interest is elevated — our consumer experience is already embedded in AI, whether it’s suggesting movies, music, or clothes, or teenagers using GPTs to do their homework. That carries through: people ask how we can use these capabilities to improve compliance. At the same time, interest in the compliance of AI is equally elevated. They don’t contradict each other, but there’s tension, because a lot of firms aren’t sure how to vet these capabilities in order to adopt them. Some have model risk management functions; regulators are beginning to lead, whether it’s the EU AI Act or recent FINRA GenAI guidance. And then there’s something talked about less: how can AI actually help? What are the good use cases? What’s smoke, and what’s real? So today we’ll cover all three — what AI can do, how we vet it to be compliant, and the best use cases and best practices for adoption. Let’s baseline with present day. Lore, within your function, how are you using AI today?

    How AI Is Used Today

    Lore: I’ll start with the broader definition of AI, not necessarily generative AI. We’ve been using traditional AI — machine learning — for our alert generation. The workhorse of communication surveillance is lexicons, keywords, and rules, and one well-known limitation of that approach is missing the context of a communication. That’s where NLP and more traditional supervised learning approaches can help provide more context into what you’re looking for. So we’re actively using that for alert generation.
    Alex: For that classic AI flavor, that typically means you’re taking your comms, your sentences, and building a model that focuses on a specific behavior out of those sentences — a very iterative process where you say “this satisfies it, this doesn’t.”
    Lore: Absolutely. And you can also use that to assist case disposition: if you have a historical corpus of what were fruitful alerts, you can train on that to look for more of that. That’s already in place, with a model risk framework around it. Now, with generative AI and the explosion of LLMs, the promise we’re looking at is again in alert generation, but with the ability to significantly account for context and attention that traditional supervised learning approaches — say, LSTM — just wouldn’t be able to do. And then in classification, summarization, and we’re also looking to explore information extraction and topic modeling. If you’re in the comms surveillance space, those are key use cases.
    Alex: Excellent. If people want to ask questions, we’ll try to answer some at the end. Alvin, over to you. A lot of banks are building enterprise agreements with AWS and using its suite of tools to experiment and build their own solutions. From your perspective, what tools are people using, and what are some real-world examples — keeping that present-day lens — of how firms use AWS within the compliance space?

    Real-World GenAI in Surveillance

    Alvin: Let me take Lore’s example and expand on it. If you look at that end-to-end surveillance process — trade surveillance or e-communication surveillance — the overall process is relatively the same. There’s the alert generation piece and the alert investigation side, where you research the alert and close it as no action required or escalate and potentially file a SAR. Traditionally, AI and machine learning have been very focused on that first area, alert generation — for example, anomaly detection for insider trading, or pattern recognition for spoofing and layering. The key problem there is an optimization problem: reducing false positives while not missing actual fraudulent activity, and machine learning is very good at that.
    Where it gets really interesting over the last year and a half is the advancements in generative AI. Now we’re seeing financial institutions use GenAI to make the second part — the alert investigation process — more efficient. One of the global exchanges integrated GenAI into their market surveillance platform, so that instead of an analyst manually searching for and collecting all the data needed to disposition an alert, the GenAI application automatically produces, in a single pane of glass, things like a consolidated table of the company’s regulatory filings, news summaries, links to companies, sentiment analysis, and more. They found that by reducing the manual effort, they saw a reduction of around 30% in the time it takes to close those alerts.
    Alex: That’s super interesting. Shlomit, over to you — our business is to add value to the use cases around regulatory compliance, but also to think ahead about how these tools can improve people’s compliance. Talk about what you’ve worked on, and let’s lean into the potential and where we see GenAI going.

    The Breakthrough: What Generative AI Now Offers

    Shlomit: Maybe I’ll zoom out and look at the development of AI technology over the past few years. Lore described the challenges and common practices of comms surveillance well — we’re looking for detection, maybe summarization, topic analysis. Technology is constantly improving: pattern analysis and machine learning, now generative AI, and we can do everything better. The next phase is investigation, and at Shield what we’re trying to do is collect information across multiple data points and produce meaningful insights — pulling together multiple communications, reporting, and analysis automatically, looking for things, suggesting follow-ups, and putting it in front of the compliance officer to pursue any risk that may have been hinted at.
    But to talk about the real breakthrough in generative AI: the jump that started with ChatGPT and the models that followed was a real leap in human-level reasoning — the ability to understand a much deeper and more complicated issue. Even in a simple detection task, the full nuances of a communication can be understood by a single model placing it together. The second thing is that generative AI is now conversational: we can interact with it and, more importantly, perform multiple steps in an assignment with an assistant that remembers the steps we did before and integrates all the information. This created the first real impression on everybody that there’s something very new here. But the second question is your question, Alex — how can we adopt it usefully? Summarization is a good example: these engines do it well, but is that the full benefit? It’s probably the first steps, and we can leverage them for much more advanced challenges.

    Summarization: Useful, but It Needs Direction

    Alex: Let me stop you so we can take a gradual approach and talk about summarization first, since Lore raised it too. What’s been interesting to me is that regulators are really doing their homework. In the EU AI Act and the recent FINRA guidance, FINRA takes the position that the controls you have are good enough — keep going — and lists examples of how AI could improve compliance, including detection and summarization. They’re not saying run into it, but these are examples where they see it being used. So let’s assume summarization is something people could lean into today. How could it be used meaningfully, and what are its limits?
    Shlomit: The challenge in summarization is that a summary is something fluffy — it’s not a yes/no answer. You can produce multiple summaries of the same conversation; some more useful, some less. For a compliance officer, a summary of a conversation can lack the specific risk that occurred, because that risk isn’t the gist or essence of the overall talk. So the question is how you direct the summarization to be beneficial for your specific needs. We have this great technology that’s very good at creating summaries, but it needs to be directed — in our case, to find or detect financial risk. You can’t just ask ChatGPT “here’s a communication, summarize it” and expect it to serve that use case. The technology is there, but to make it useful you need to do more manipulation, add more information, and put more controls in place.
    Lore: That’s a key point. One clear use case: a communications alert can go on for multiple exchanges in a chat, a mix of business talk and casual conversation. If we can prompt it the right way to summarize what we’re looking for, that assists the surveillance analyst. With the lexicon approach, you know exactly why it flagged, because the words are there. Here, it’s more about context, so a good summary can add explainability or reasoning about what you should initially look for.
    Alex: The key question with summarization is whether it adds value or adds work. Is it creating two steps, or creating less work? Ideally the latter — a piece of data that gives better at-a-glance insight so you can make a quicker decision. Another thing that’s harder to vet, because there’s so much out there, is whether something actually works for you. Could you just plug this into ChatGPT yourself and ask it a piece of trade jargon? Or is a capability you’re being sold meaningfully adding value? Alvin, since your view is more generalized, how do you help firms zero in on the decision they need and vet these use cases?
    Alvin: Largely, we see customers leveraging generative AI for internal-facing use cases. It’s the Iron Man analogy — GenAI is the suit, making the person better. If you need to get information, GenAI can grab it, summarize it, and collate it, so you don’t have to go to three different data sources. If you need to summarize an eighty-page earnings transcript down to three paragraphs, it’s very good at that. The exchange example I gave is doing this today and reducing alert-resolution time by 30%. The question is how trustworthy it is — can you trust that summarization? There are techniques now that link the output generated by the GenAI right back to the original sources, so you have trust within the system.

    LLMs as Classifiers and Topic Modeling

    Alex: Lore, you started to talk about LLM classifiers. How do you see those changing the work you’ll be doing in the next year or two?
    Lore: When we build surveillance scenarios, we’re really putting pieces together, and you can have classifiers that detect certain indications of behavior. Take secrecy — how would you detect a note of secrecy in a text? Traditional machine learning feeds it examples, but the promise of an LLM as a classifier is whether it can detect the nuances in the tone of a conversation better. We have a number of examples and ground truth to compare against, plus a challenger model in our existing ML. Another is topic modeling: the simple question of whether this is trade talk or casual conversation, or deal talk. We have techniques that try to do that, but LLMs, because of the corpus they’re trained on, are potentially going to be better at it. One thing I’d note across summarization and classification: be mindful of how accuracy relates to the length of the input text. Is there degradation the longer the input you give it? That’s a consideration folks should keep in mind.

    Controls, Governance, and Model Risk Management

    Alex: That’s a good way to start talking about controls and governance. We have two parallel functions, both compliance functions in a sense. There’s the model risk management (MRM) function, which vets models across a firm — Lore, you’ll have been through that process of getting your models approved. And there’s the question of compliance teams becoming comfortable with the idea of AI; some banks now have AI policies. What we’re seeing is that MRM functions are quite mature but haven’t quite adjusted to how they should vet LLMs, in part because the supervised model you’ve given them let them understand: “If it comes from this dataset, I can follow how you came up with these answers.” Lore, what’s been the hesitation internally around leaning into LLMs?
    Lore: I’d say it’s not so much hesitation as reasonable caution. There are risks in generative AI — hallucination, privacy, potential fairness and bias based on the data it was trained on, and data limitations, since it’s trained as of a particular date, so accuracy is conditioned on that. But there’s general openness to adoption. The MRM piece has to look not just at the traditional things — soundness, potential bias — but also at hallucination, transparency, and explainability. We know how to do explainability for the more traditional models; it’s less clear for a classifier you’ve built by focusing a big GenAI engine on something in particular. These are things you have to test: when you say “is this small talk?” you need to validate it, look at the accuracy of the output, segment your data across categories, and make sure there’s consistency in how it’s predicting. We’re not starting from scratch — there’s a whole body of experience we can draw from.
    Shlomit: The new technology puts new challenges in front of us. When we evaluate accuracy, there’s how do I evaluate it, but also how do I influence it? In classical machine learning you can retrain a model. In generative AI, with the big models currently released, the way to influence the model is less direct and the way to validate results is different. ChatGPT might produce a summary that’s completely relevant — how do you validate it? You can’t just retrain or influence it directly. You need to put guards and controls in place: ask it multiple questions, use multiple agents and multiple ways of framing the question, and validate against external data sources. For example, if it says “there is inside information here,” maybe I put the definition of inside information in front of it and ask, “Are you sure this matches?” Advanced reasoning models are very good at chain-of-thought — rethinking their entire decision process and reproducing an answer. These are the kinds of controls you need today.
    Alex: Are you putting the onus on the vendor or the firm?
    Shlomit: When a vendor releases a product like that, it’s their responsibility — you can’t offer a product that creates hallucinations for the customer. But ultimately our customers are big financial organizations exposed to regulation, so they need all the relevant documentation, metrics, evaluations, testing, and ongoing monitoring to show the regulator the models are up to their needs. And the concerns aren’t only hallucination and accuracy. We see in regulations — FINRA started talking about it, and the new EU AI Act coming in the next couple of years — that the fact that we have a far more robust and powerful technology is scaring everybody: how much more danger can it put me in? The EU AI Act measures the risk of AI not only by the robustness of the model but also by the use case — what are you trying to do, will it affect the workplace, will it affect privacy?
    Alex: That’s why we’ve seen risk profiles come into the conversation — the long-standing question of whether we can develop a risk profile, “know the next LIBOR before the LIBOR.” The EU AI Act specifically calls out risk profiles, and that regulation is still being refined, so some use cases may be harder to get across than others.

    Handling Hallucinations: RAG, Lineage, and Chain of Thought

    Alex: Alvin, you and I talked about other controls people can put into their models — RAG and others.
    Alvin: For those not aware, a hallucination is when the large language model just makes something up — if it doesn’t know the answer, it invents one. For obvious reasons, that’s a big concern in financial services. A good mental model is to treat the LLM as a person. First, let the LLM know that “I don’t know” is an acceptable answer — simply tell it, “If you don’t know, say I don’t know instead of making something up.” Second is the RAG approach — retrieval augmented generation — which is essentially an open-book test for the LLM. You provide a data repository for it to reach into. One customer hooked up their trading rule book to an LLM so traders can ask, “What are Q orders?” or “What’s the regulation around X?” and the model reaches into that repository. Updating it is a very light lift — if a regulation changes, you just upload the most recent document; you don’t retrain the model. The second benefit is lineage: just like a colleague, if you don’t like the answer, you ask, “Where did you get that?” and the LLM can point you to the document. And it can show its chain of thought — the step-by-step process of how it synthesized the information and reached its conclusion. So, mental-model-wise: treat the LLM as a human — if you don’t believe the answer, ask where it got the information and how it arrived at its conclusion.
    Alex: The change in mindset we’re all harping on is that the efficacy of these models is being measured by their outputs, rather than by their lineage — the datasets they were trained on, which are harder to understand. In Lore’s world not long ago, you could say, “These are the twenty thousand emails I used to train this model, and these were the sentences,” and someone could hold that and feel they understood how it became what it is. The hard leap is: if I don’t know where it came from, how can I be comfortable with what it’s telling me? What we’re all seeing is that there are ways to measure that, and controls you can put in place — the lineage of the information, the prompts baked in, and ultimately the merits of the output: does it actually meet what it was asked to do?
    Lore: I really like Alvin’s “treat it like a human” analogy. In traditional ML you have scores — likelihoods, how close it is to what you trained it on — so you can alert on the highest-scoring ones. That’s a measure of confidence. If you ask the LLM, as a person, “How confident are you in your answer?” — do we have a metric for that?
    Shlomit: The first thing discovered about ChatGPT — and the jokes on social networks — is that it will tell you everything with great confidence; it’s sure of its answer. The advancements over the past year, through the chain-of-thought process, are its ability to reflect and rethink given additional information or the question framed from different angles. I can ask where it retrieved the document from, but I can also ask it to look inside the regulations and make sure it made the right decision according to the definition there, not just its own knowledge. So there are many techniques to increase our confidence — it’s not exactly the same as a confidence score from the model, but making it answer again, asking differently, producing a critic agent, and forcing it to look at additional information.
    Alex: I’d add one basic element: QA. People think of this journey as binary — you flip a switch and everything looks different — but firms should walk there. As Lore said, these are ultimately risk-based decisions. With a lexicon, I might look for the word “rumor” and know I miss every misspelling or the European spelling — I’m missing a lot, but I know what I’m getting. With a supervised model, I set a threshold and know there are always a few sentences below it that kind of look like what I want, but the risk-based decision is to look at everything above the threshold. We’re not asking people to make a fundamentally different decision — it’s just making the switch to how we develop those controls.

    Audience Q&A: ChatGPT vs. Copilot Use Cases

    Alex: We have a question: in your collective view, ChatGPT versus Copilot 365 in day-to-day compliance operations? We can use both, but most team members are struggling with use cases — could you provide specific examples?
    Alvin: I’ll give two. One is a simple Q&A chatbot against rules and regulations. If you’re a global bank interacting with hundreds of regulators, all with different rules across regions, you can put all of that into a data store, hook up an LLM, and get answers in natural language — “What’s the trading rule in Zimbabwe?” I’m hand-waving; setting up a data store and an embedding model has real complexity, but high-level, that’s one use case. The other is alert disposition: for a front-running or insider-trading alert, you need to collect data from multiple sources — company filings, old investigations — and you can use GenAI to grab and summarize all that, reducing manual effort. These are two use cases actually in production at financial institutions today. The only other thing I’d add is coding assistance — collaborative coding with a Copilot is a known, productive use case that helps time to market.
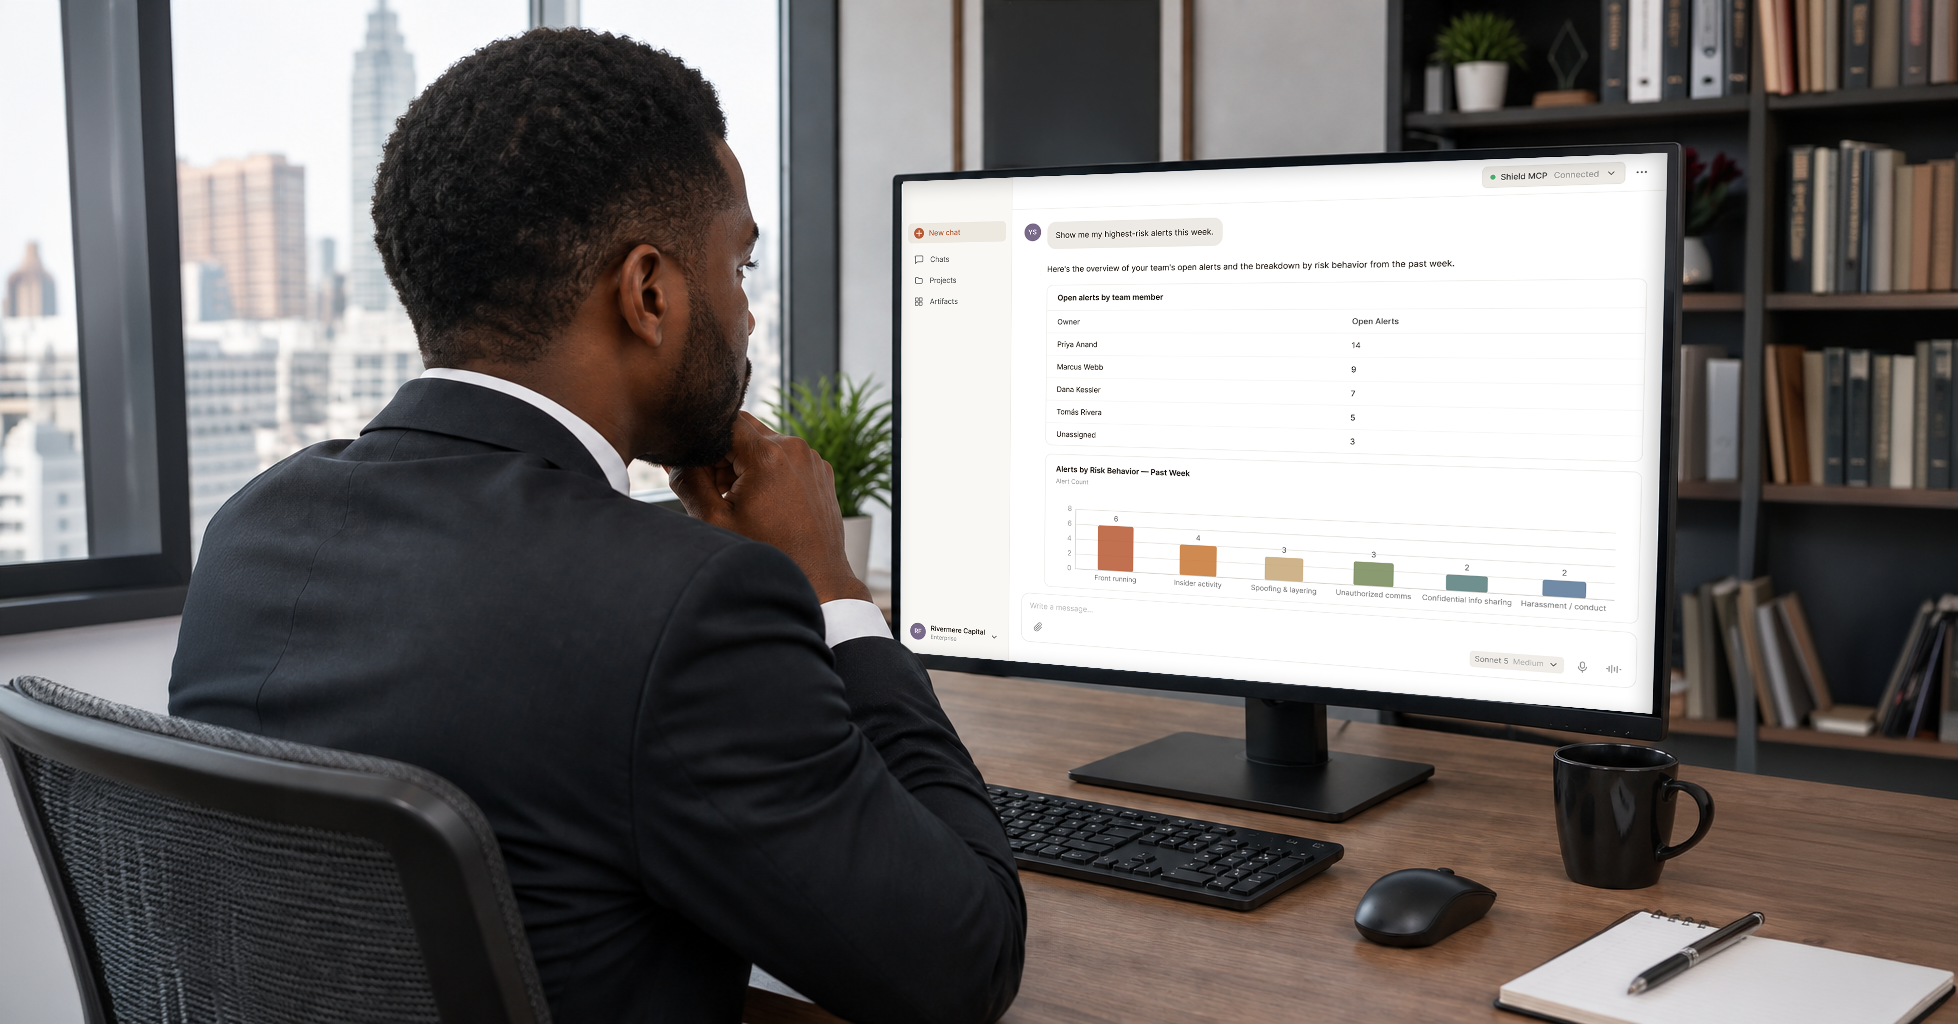
    Shlomit: In general, organizations should already have a connection to ChatGPT or Copilot, or both — it’s a matter of convenience and security. The main difference and the main advance ahead: when you have a connection to a large model, it depends on you having a question and wanting a direct answer — like looking in Google, now we ask ChatGPT. But the future is platforms and products that don’t require you to think of the question. The platform itself will initiate and collect information for you, surface risks, and make decisions even before you know you have a question. So when you know you have data missing or a coding question, ChatGPT is the way to go. But incorporating it into products requires an additional leap — the product leveraging it without you having to initiate the question, just putting it in front of your eyes.

    Best Practices: Defining Value and ROI

    Alex: Let’s segue into use cases and best practices. We tend to think of the whole first — “show me LIBOR, show me something that already happened, help me see the future” — which isn’t a useful approach to this technology, because it’s too muddled a way to get to an answer. How do we focus our use cases so people can meaningfully leverage and experiment with AI?
    Alvin: Take your usual approach: have a well-defined problem you’re looking to solve, then see which technology helps. Don’t use GenAI as a hammer where everything looks like a nail — sometimes traditional machine learning or basic analytics solves it, sometimes you need generative AI. The biggest shift over the last twelve to eighteen months: eighteen months ago, people wanted to boil the ocean — “GenAI can do multiple things, let’s solve all these problems.” Now people are more focused on return on investment: if I apply GenAI to this use case, what’s my ROI? All the examples I gave have a well-defined ROI — saving x amount of time, reducing manual effort by 30%. A call center use case is another: if you reduce call time from twelve minutes to four, you know exactly how much you’ve saved.
    Alex: ROI also means appreciating how much it costs to crunch all this data through these machines. Our consumer experience of just asking a question and getting an answer feels easy, but doing some of these things at scale across all of a bank’s comms is really expensive. Unless the output merits that cost, it’s hard to justify the leap.
    Alvin: So what’s the implication? Every function in a large bank can’t wait to experiment. What we’ve found useful is having a governing body — a centralized process that knows all the potential use cases, evaluates them consistently across dimensions of risk, productivity, and likelihood of success, and decides which to start with. That gives you a systematic, transparent process for governing your GenAI journey.
    Lore: We have a center of excellence that, even before GenAI, had principles for the ethical use of AI — human centricity, fairness, privacy, explainability. If you apply that lens enterprise-wide, it really helps, because I don’t want to be restricted to the knowledge of surveillance alone; other domains that have used this can inform how I use it.
    Alex: Does that ever hobble experimentation, given how much of this is new?
    Lore: The spirit of the data scientist is to jump into it, but it’s reasonable to be aware of the risks and address them. So it hasn’t — it could have been faster without governance, but there’s a cost to not having appropriate governance, because regulation is existing and forthcoming. There’s genuine cost to these things if you’re not prudent in your adoption.
    Shlomit: In the evolution of GenAI, first everybody was amazed, then came fear, and regulation started to acknowledge it’s here and how to handle it. Now the focus is value — how do I get real value? The first use cases are trivial: summarize, give me answers. The more challenging ones are how it will make decisions for me and do the work behind the scenes. That’s where the real value comes — not only doing what we do better, but looking at the problem from a different perspective. Alex, I heard you once suggest that instead of looking at alerts in communications, let’s look at risks. Now that we can collapse information across alerts, why are we looking communication by communication? That’s the change the new technology will bring — but the correct judgment of it is ultimately how much value it gives.

    Closing

    Alex: Alvin, any last thoughts?
    Alvin: I have nothing more to add to what Shlomit and Lore said.
    Alex: If we’ve covered a few things today: we’ve looked to refine the value, so people think squarely through what the actual value is. We’ve emphasized that controls exist and are maturing around how we measure that value, and that firms and vendors need to lean into establishing those controls, showing them around, and iterating on them so people become comfortable. And on the other side, as firms look to adopt, what are the best use cases — educating themselves, working in partnership with whoever has these capabilities, and not being afraid to experiment, as long as they document what they did. I feel like we could go on and on, but I’m really grateful for this panel and this discussion. Thank you all for listening, and have an amazing day.

Q&A

Do regulators actually allow us to use AI in surveillance?

Yes. Recent FINRA guidance takes the position that firms’ existing controls are good enough, and it lists detection and summarization as examples where AI is already being used in compliance. The EU AI Act goes further, scoring risk not just by the model’s power but by the use case. The catch is documentation and governance — you need to show a regulator your metrics, testing, and monitoring.

What’s the difference between traditional AI and generative AI in surveillance?

Traditional machine learning is very good at alert generation — anomaly detection for insider trading, pattern recognition for spoofing — where the goal is reducing false positives without missing real activity. Generative AI shines on the investigation side. One global exchange integrated GenAI into its market surveillance platform to auto-collect the data an analyst needs, cutting alert-closing time by around 30%.

Can we just use ChatGPT to summarize flagged conversations?

The technology can summarize well, but a generic summary often misses the point for compliance. A conversation’s risk usually isn’t its “gist,” so an unguided summary can leave out the exact thing you care about. To be useful, summarization has to be directed with prompts and controls toward your specific need — detecting financial risk — not just producing a tidy recap.

How do we deal with AI “hallucinations”?

Treat the model like a person. First, explicitly tell it that “I don’t know” is an acceptable answer instead of inventing one. Then use retrieval augmented generation (RAG) — an open-book test where the model pulls from a data repository and can cite the source document. Ask it to show its chain of thought, validate answers against external references, and add basic QA. Layered controls, not blind trust.

How do we get an LLM past our model risk management team?

Expect a mindset shift. MRM teams are used to vetting models by their lineage — the dataset and sentences they were trained on. With LLMs, you validate by outputs instead: test accuracy, segment your data across categories, and check the model predicts consistently. You’re not starting from scratch — the soundness, bias, transparency, and explainability disciplines carry over, with hallucination added as a new dimension to test.

Which is better for day-to-day compliance work, ChatGPT or Copilot?

It depends on the use case, and narrowing the focus matters. Strong, in-production examples include a Q&A chatbot over your own rules and regulations (built with RAG so it cites sources), alert disposition that gathers and summarizes data from multiple systems, and coding assistance to speed development. Don’t point it at “the whole bank” — load a specific corpus and test what performs.

How do we pick AI use cases actually worth pursuing?

Start with a well-defined problem, then choose the technology — don’t treat generative AI as a hammer where everything looks like a nail; sometimes traditional ML or basic analytics wins. The big shift is from “boil the ocean” to clear ROI. Good use cases have measurable returns, like cutting call-center handling from twelve minutes to four, and they justify the real cost of running models at scale.

How do we govern AI adoption without killing experimentation?

Set up a central governing body or center of excellence that inventories potential use cases and evaluates them consistently across risk, productivity, and likelihood of success — ideally against pre-existing ethical-AI principles like fairness, privacy, and explainability. The panel framed the mood as reasonable caution, not hesitation: experimentation continues, but with documentation, because regulation is here and forthcoming.